Introduction
Global computer setups run nonstop to keep everyday mobile applications alive. Every server produces massive mountains of telemetry notes each minute. Human administrators cannot inspect all these numbers without fast algorithmic help. This practical breakdown introduces Artificial Intelligence for IT Operations in very friendly language. Readers discover how smart algorithms detect hidden code bugs early. You also see how self-healing recipes revive fallen services in seconds. Curious learners pick up fundamental skills for handling distributed setups. Finally, visiting TheAIOps.com connects technical learners with top instructional material.
What Is AIOps?
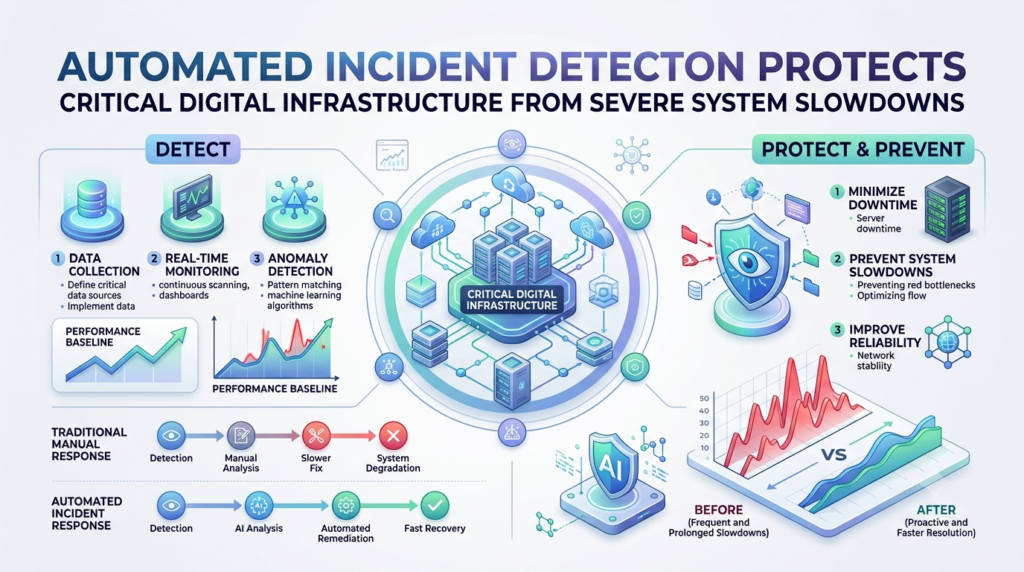
Artificial Intelligence for IT Operations blends clever machine math with daily system maintenance. Industry specialists contract this phrase down to AIOps. The phrase IT operations describes all the hard work that keeps servers running. Active programs write constant diary lines known as logs. Hardware devices also track quantitative efficiency digits called metrics. Abrupt status variations dispatch short broadcast bulletins known as events. Standard monitoring platforms track these vital signs continuously. When parts fail, loud notifications named alerts flood engineering phones. Advanced software processes these noisy warnings using machine learning methods. Machine learning enables software to uncover subtle trends without custom programming. Next, the tool executes root-cause analysis to find the main culprit. Autonomous scripts launch prompt recovery actions to heal the host.
Why Do IT Teams Need AIOps?
Enterprise companies place vital software across vast server clusters worldwide. These expansive environments generate billions of operational signals every single morning. On-call technicians face terrible alert fatigue because bogus alarms ring constantly. Support staff spend whole shifts searching through endless error text manually. Sluggish repair jobs hurt team morale and upset waiting customers. Identical defects surface repeatedly because nobody investigates deep baseline flaws. Support crews need early warnings before full system outages hit. Intelligent platforms group related signals together so operators spot primary issues immediately. This method eliminates bad system changes and protects employee time. Even so, clever software cannot solve every operational puzzle alone. Human engineers must always make high-stakes architecture choices.
AIOps Tasks and Benefits
| AIOps Task | Simple Meaning | Possible Benefit |
| Signal Ingestion | Pulling logs and numeric metrics | Gives administrators a unified view of machine state. |
| Noise Reduction | Silencing duplicate and minor pings | Lets engineers concentrate purely on real emergencies. |
| Deviation Finding | Catching strange fluctuations in data | Flags simmering defects before critical software fails. |
| Alarm Merging | Linking connected error messages | Points out the initial failure that broke other apps. |
| Auto Healing | Running pre-approved patch scripts | Restores frozen services without human keyboard entry. |
What Does TheAIOps.com Offer?
Engineering teams require straightforward documentation to modernize their operational capabilities. TheAIOps.com publishes dependable educational guides for entry-level and experienced technicians. Inquisitive minds discover structured AIOps Training modules that develop strong maintenance habits. A thorough AIOps Course breaks down primary diagnostic principles and practical drills. Ambitious specialists review materials for industry-recognized AIOps Certification credentials. The portal surveys leading AIOps Tools that monitor enterprise cloud setups. Companies study honest breakdowns prior to adopting an enterprise AIOps Platform. Businesses can also look into specialized AIOps Consulting alongside custom AIOps Services. Detailed tutorials steer technical squads through every phase of an AIOps Implementation. Every future AIOps Engineer discovers clear blueprints for expanding workplace skills.
AIOps Training and AIOps Course
Sound technical education starts with clear foundational ideas. Trainees entering an AIOps Course observe how core system utilities build event logs. They inspect metric trackers that evaluate storage capacity and chip heat. Learners apply alert management methods to wipe out distracting background noise. Guided exercises show how anomaly detection flags wild spikes in visitor traffic. Interactive workshops teach root-cause analysis by connecting failed checkouts to stopped services. Students also write short Python programs that trigger safe container restarts. Isolated test environments let students break and mend mock server arrays safely. Real case studies explain how huge streaming portals survive giant traffic rushes. Regular terminal practice turns book theory into genuine troubleshooting mastery.
AIOps Learning Areas
| Learning Area | What Learners Should Practice |
| Log Ingestion | Parse messy computer outputs to find recurring error patterns. |
| Metric Plotting | Chart disk space, memory limits, and data flow over days. |
| Alert Filtering | Strip out repeated warning messages to maintain clean dashboards. |
| Outlier Detection | Configure baseline models that spot unexpected traffic plunges. |
| Defect Tracing | Follow an abandoned user basket back to a dead network port. |
| Self-Repair Tasks | Deploy tested command scripts that clear out bloated cache folders. |
| Multi-Cloud Watching | Combine telemetry streams across distinct cloud providers. |
| Incident Sharing | Route summarized problem updates straight into internal chat software. |
AIOps Certification and AIOps Engineer Skills
An AIOps Certification signals that an applicant grasps automated infrastructure methods. Studying for rigorous exams organizes central operational subjects into a clean framework. However, displaying a paper credential never ensures immediate hiring success. Hiring managers seek real-world diagnostic ability and proven scripting competency. A talented AIOps Engineer tracks intricate cloud ecosystems with absolute confidence. They untangle confusing software snags under intense outage pressure. They code resilient automation scripts that remove boring administrative duties. Top practitioners also grasp elementary data science concepts and basic algorithmic principles. Clear verbal skills help technicians explain outages to executive leaders plainly. Building custom side projects demonstrates that you can defend active production environments.
AIOps Tools and AIOps Platform
Operations crews pick specialized toolsets to protect business continuity. Elementary monitoring utilities verify if local servers accept outside connection pings. Deeper observability engines trace customer interactions across multiple microservices. Central log collectors store millions of timestamped lines from hundreds of virtual hosts. A modern AIOps Platform unites all these input streams under one analytical roof. Incident management setups alert the proper on-call staff during real crises. Organizations evaluating new AIOps Tools must check core business targets first. Managers need to confirm that fresh tools link smoothly with active software pipelines. Directors must check total licensing expenses and demand strict customer safety measures. Ultimately, chosen platforms must expand effortlessly as commercial network traffic climbs.
AIOps Implementation: How Does It Work?
System architects start an AIOps Implementation by targeting a single troublesome service. First, extract structured metrics from that chosen target application. Configure monitoring agents so diagnostic data feeds the central repository cleanly. Next, install strict suppression filters that drop useless system chatter. Allow algorithmic models to learn standard operating trends across full business weeks. Run experiments to verify that anomaly detection catches actual performance drops. Then, unite connected failure warnings to display the root defect immediately. Code small self-repair tasks for safe work, like purging temporary folders. Include compulsory human approval checkpoints before software touches essential customer databases. Measure incident response gains, improve your correlation policies, and expand gradually.
AIOps Consulting and AIOps Services
Growing companies frequently hire specialized advisors when installing smart telemetry systems. Professional AIOps Consulting protects executive teams from costly architecture traps. Specialized agencies deliver AIOps Services, including extensive audits of current network visibility. Consultants help managers pick software that fits their practical corporate resources. Experienced specialists also build reliable data pipes between older diagnostic tools. Skilled mentors teach internal staff so permanent employees manage tools comfortably. They also set up secure remediation scripts to avoid accidental data loss. Still, organizational leaders must outline clear goals before signing consulting deals. Knowing your biggest operational headaches ensures you spend your capital wisely.
Real-Life Scenarios / Experiences
- An online ticketing marketplace suffered recurring website stalls during popular concert releases. Unprecedented waves of eager fans crashed the payment interface immediately. The smart monitoring platform identified abnormal database congestion inside four seconds. It spun up five supplementary cloud servers and stopped a disastrous crash.
- A nationwide pharmacy chain logged three thousand panic notifications following an automated firewall upgrade. Shocked engineers panicked as diagnostic monitors lit up with red lights. The automated platform grouped all three thousand alerts into a single ticket. It steered technicians straight to one wrong rule setting on switch number three.
- A digital publishing house watched a file server near total capacity during a live news broadcast. The self-healing script noticed the dangerous storage trend half an hour early. It moved old video archives to cold storage without waking any sleeping worker. The morning crew reviewed the automated incident summary during regular office hours.
How TheAIOps.com Can Help
Understanding automated network operations demands continuous practice, clear blueprints, and dependable resources. TheAIOps.com offers system administrators and project leaders clear educational assets. Readers can review thorough AIOps Training tracks to improve operational capability. Learn how an AIOps Course simplifies telemetry, trend discovery, and automation. If you wish to demonstrate your skills, review our AIOps Certification guides. The site evaluates commercial AIOps Tools to help businesses select suitable software. You can also explore expert advice on AIOps Consulting and complete AIOps Services. The platform explains each phase of an AIOps Implementation in basic terms. Rely on these learning materials to grow into a skilled AIOps Engineer.
A Practical Implementation Approach
Direct your pilot project toward one unstable software component. Pinpoint the crucial telemetry feeds and event logs required to investigate crashes. Route those specific data lines straight into your analysis engine. Configure strict filtering guidelines so daily operational chatter drops off dashboards. Next, test your anomaly detection engine against previous failure records to confirm accuracy. Build your initial automated response for a simple, low-risk server task. Maintain manual verification buttons for events that alter customer account records. Measure your recovery speed to confirm genuine diagnostic improvements. Refine your alert correlation logic through weekly meetings with frontline administrators. Roll out your smart operations framework to secondary applications only after scoring clear early wins.
Common Mistakes to Avoid
Trying to automate every single operational process immediately triggers severe network crashes. Many companies feed messy, unformatted logs into predictive tools, distorting output accuracy. Another common mistake involves buying pricey software suites before defining explicit engineering needs. Organizations frequently forget team culture, causing technicians to fear automation out of job insecurity. Running untested repair routines without manual confirmation flags can wipe out active customer records. Some teams launch algorithmic models without testing baseline performance against previous outage records. Other companies overlook employee training, letting expensive software packages sit abandoned on quiet monitors. Finally, leaders often forget to track mean recovery metrics, making future tooling budgets impossible to defend.
Frequently Asked Questions
1. What does AIOps mean in simple words?
Advanced software monitors server records day and night to shield applications from crashes. The platform identifies system glitches instantly and triggers self-repair actions. This mechanical vigilance preserves system reliability for everyday online shoppers.
2. Is AIOps meant to replace human IT engineers?
Automated platforms never eliminate human computer workers. They simply handle exhausting duties like scanning endless rows of plain text. This division of labor frees engineers to build better software and solve unique bugs. People always make the final decisions during major operational emergencies.
3. What is the difference between DevOps and AIOps?
DevOps describes a cultural movement that unites software creators with operational teams. AIOps refers to smart software packages that process raw telemetry data. Teams embed intelligent diagnostic tools directly inside DevOps pipelines to speed up daily repairs.
4. Which programming languages help an AIOps Engineer most?
Python remains the best choice for modern infrastructure workers. Specialists write Python to parse messy data lines and communicate with predictive models. Practicing elementary Linux shell scripting also helps technicians automate daily maintenance chores quickly.
5. What are the three main types of operational data?
Active operating systems generate metrics, event records, and distributed traces. Metrics record quantitative performance measurements like CPU heat over time. Logs contain timestamped status summaries created by software. Traces track a single visitor click as it passes through separate back-end machines.
6. Can small companies benefit from using smart IT operations?
Small firms gain immense benefits if they run complicated multi-cloud systems. In contrast, tiny offices running simple websites on one local machine do not need predictive analytics. Basic monitoring scripts handle small workloads fine until company user traffic grows much bigger.
7. What is alert noise in computer operations?
Alert noise describes thousands of non-fatal notification banners spamming an engineer’s phone screen. Most of these messages flag temporary hiccups that heal without human input. This annoying storm conceals genuine system outages and drains engineer focus.
8. How long does a standard system rollout take?
Deploying a smart platform for a single target application takes three to six months. Teams spend this time sorting data, tuning rules, and testing automated scripts. Rolling out the framework across a multinational company takes over a year.
9. What does root-cause analysis mean for servers?
Root-cause analysis hunts down the primary defect that caused several other programs to fail simultaneously. For instance, a locked database table can break dozens of dependent store pages. The smart tool points operators straight to the locked database rather than the individual store pages.
10. Do I need a math degree to learn these tools?
Nobody needs an advanced university math degree to master smart operational tools. Modern enterprise platforms run complex statistical calculations in the background automatically. Engineers just need to know how to interpret dashboards, adjust rules, and write simple scripts.
11. What is automated remediation in modern computing?
Automated remediation refers to system programs fixing broken servers without manual human steps. For example, a background script restarts a crashed process whenever memory consumption crosses ninety percent. This instantaneous recovery keeps platforms online without waking workers at night.
12. How does anomaly detection help site reliability teams?
Anomaly detection models calculate typical performance baselines during standard workdays. The software flags strange behavioral deviations, like sudden midnight transaction drops. This timely notice lets technicians repair faulty code before shoppers notice broken pages.
CONCLUSION
Enterprise network architectures expand continually, and mechanical automation provides the leverage teams need to maintain control. Pairing machine learning with operational data silences distracting alarms and flags hidden defects before users notice delays. Developing these technical capabilities equips specialists to defend critical online platforms from total outages. Beginners can learn practical scripting, inspect server event logs, and build dependable troubleshooting habits. Web portals like TheAIOps.com provide instructional roadmaps, tool analyses, and structured training materials to guide your professional progress. Start your transition with small operational wins, test self-healing scripts cautiously, and maintain human control over vital applications. Consistent hands-on experimentation transforms ambitious students into reliable modern system guardians.
