Introduction
Flawless information empowers modern enterprises to design winning products, delight shoppers, and boost profits every single day. Corrupt files spark bad choices, disrupt delivery schedules, and generate costly accounting errors across departments. When morning performance sheets stall or display twisted numbers, team leaders waste critical hours arguing over facts. Today, forward-thinking organizations build sturdy automated tracks so records move without any manual blunders. In this fresh manual, you will explore essential operating principles, popular software choices, and lucrative technical careers. You can also visit TheDataOps.org to find structured learning resources that sharpen your data pipeline abilities.
What Is DataOps?
Imagine municipal aqueducts delivering crisp mountain spring water directly into thousands of residential kitchen faucets. In enterprise computing, businesses shift consumer transaction logs from cash registers into massive cloud storage vaults. Yet digital pipes often develop leaks, lose valuable records, or pick up messy errors along the journey. DataOps establishes a cohesive discipline where engineers, explicit steps, and rapid script verifications join forces. It borrows nimble practices from software creators so platform architects and desk analysts share priorities without friction. Teams dismantle bottlenecks quickly, automate tedious routines, and supply spotless records on a dependable schedule.
Why Does DataOps Matter?
Enterprises rely on exact metrics to balance ledgers, stock retail shelves, and distribute employee payroll on time. Without deliberate pipeline care, transmission speeds slow to a crawl and critical sales summaries arrive days late. Occasionally, entire database views disappear outright, leaving senior executives completely blind to customer behavior patterns. Stressed employees waste entire afternoons fixing spreadsheet cells by hand instead of creating exciting commercial offerings. Friction between database builders and department analysts triggers endless frustration alongside missed project deadlines. A thoughtful operational approach avoids these catastrophes by intercepting faulty numbers before any consumer notices.
What Is TheDataOps.org
TheDataOps.org operates as an open digital academy for curious technology beginners and seasoned systems professionals alike. The platform features clear design blueprints, practical study guides, and sequential walk-throughs for real workplace challenges. Its primary purpose centers on demystifying contemporary pipeline operations through straightforward language that anyone can follow. Readers learn how to eliminate manual chores through clever automation, explicit validation rules, and proven tools. Whether you direct an enterprise engineering department or study independently after work, this destination delivers dependable advice.
DataOps Training and DataOps Course
Registering for DataOps Training helps motivated professionals construct durable, self-healing channels for mission-critical enterprise numbers. Participants master agile collaboration habits, DevOps routines, and rapid continuous delivery patterns known as CI/CD. They also gain direct experience validating records, configuring cloud clusters, and tracking transmission latency during peak hours. Enrolling in an immersive DataOps Course provides realistic laboratory assignments rather than boring slides and static definitions. Resolving actual broken pipeline scenarios builds genuine confidence before you step into a fast-paced development office. You can discover structured curricula and skill guides on TheDataOps.org to elevate your day-to-day engineering craftsmanship.
Comparison Table
| DataOps Area | Main Goal | Example Activity |
| Data Pipeline | Move data | Load daily sales data |
| Automation | Reduce manual work | Run jobs automatically |
| Testing | Find errors | Check missing values |
| Observability | Watch systems | Track failed jobs |
| Data Quality | Improve data | Check data rules |
| Orchestration | Manage steps | Run jobs in order |
DataOps Certification
Obtaining a reputable DataOps Certification demonstrates your comprehensive mastery of automated workflows to hiring authorities. This credential confirms that you know how to write validation checks, automate script rollouts, and transfer records smoothly. Still, a paper diploma never substitutes for the deep intuition you acquire through direct terminal work. Astute students balance certification exam manuals with hands-on scripting tasks, assembling prototype pathways that process messy records cleanly. Begin your path by drafting basic scripts, provisioning database tables, and engineering checks that block corrupt rows.
Data Pipeline Automation
Data Pipeline Automation relieves human professionals from repeating mundane keyboard clicks and shifting files between server directories manually. Instead, computers execute continuous data sequences following six distinct stages: Collect, Clean, Test, Process, Store, and Monitor. For instance, an electronic bookstore ingests overnight reader purchases, strips out duplicate entries, and validates order amounts instantly. The operating environment calculates final tallies, commits clean ledgers, and oversees background performance autonomously. Automated deployment engines trigger these validation suites the moment an engineer commits any adjustment to pipeline code.
DataOps Tools
Technical teams assemble specialized DataOps Tools to construct, evaluate, and monitor their interdependent data highways. Programmers choose Python to author compact scripts that normalize messy strings and recalculate complex aggregates. Apache Airflow functions like a central flight controller, launching distinct pipeline tasks in an orderly, deterministic sequence. Apache Kafka streams real-time messages instantaneously, while Apache Spark crunches colossal datasets across linked computer networks. Jenkins runs automated regression checks, Grafana presents dynamic system metrics, and Tableau renders business trends transparently. Because no single business requires every available program, engineering leads select assets matching their budget and requirements.
DataOps Platform
A modern DataOps Platform consolidates dispersed pipeline components into a single, cohesive command console for the entire department. It connects ingestion connectors, conversion jobs, validation tests, task planners, health telemetry, visualization layers, and access privileges. Technical specialists oversee the complete transmission landscape through one unified interface instead of juggling multiple separate web applications. Robust platforms help operators isolate broken entries promptly, launch pipeline revisions safely, and safeguard confidential consumer information. Prior to signing vendor agreements, cautious managers assess subscription costs, engineering support, configuration simplicity, and organizational expansion targets.
Data Observability
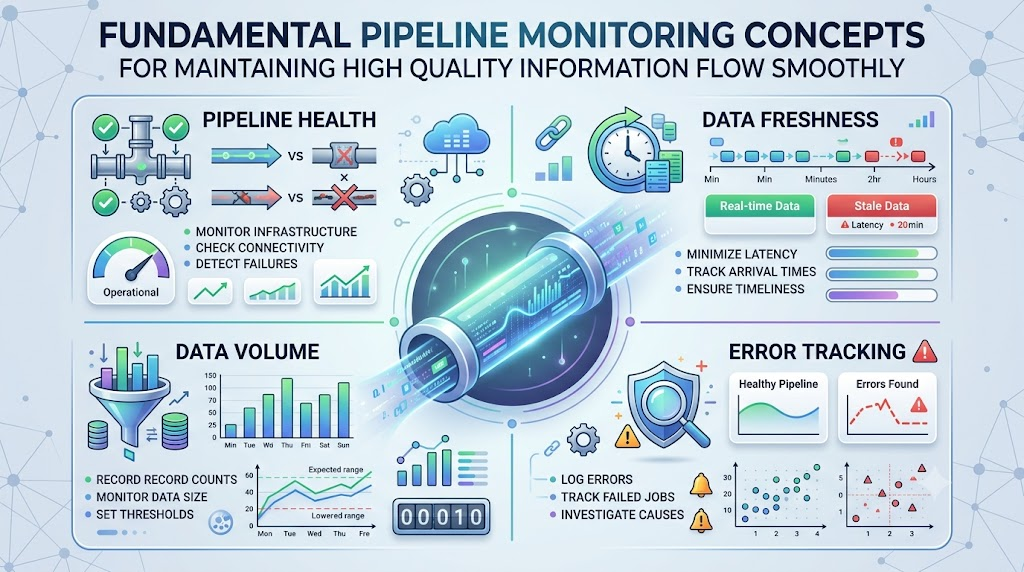
Data Observability grants technicians deep visibility into the internal operational state of their live data pipelines. It monitors system stability, transfer speed, missing fields, unexpected process crashes, payload size, and server latency. Picture a bustling ticketing site that typically logs twenty thousand transactions hourly suddenly recording zero reservations. Observability watchers register this unnatural pause immediately, dispatching emergency alerts to technicians on duty. Because the group catches the problem early, they can mend damaged endpoints before morning business meetings begin.
Data Quality Management
Data Quality Management preserves information accuracy, consistency, and integrity so executives can make sound strategic investments. Ingestion pipelines often encounter troublesome anomalies such as empty attributes, mismatched regional dates, duplicate rows, and clipped strings. When polluted inputs slip past gatekeepers into management summaries, executives launch ill-advised campaigns based on faulty figures. Automated quality filters measure incoming payloads against strict structural rules before committing any record to permanent warehouses. Enforcing these automated validations cultivates lasting confidence between platform developers and executive teams who consume reports.
DataOps Consulting
Organizations that experience chronic system slowdowns frequently engage seasoned DataOps Consulting professionals to overhaul their operational frameworks. External mentors inspect daily operations, diagnose lingering pipeline defects, and flag repetitive manual copying rituals across departments. They assess testing coverage, warning systems, orchestration software, and baseline hygiene protocols throughout the technical footprint. Trustworthy advisors formulate practical, stepwise remediation plans targeting genuine system chokepoints without offering flamboyant promises of magical overnight turnarounds. Their practical counsel enables internal teams to publish reliable dashboards promptly while minimizing cloud hosting costs.
Real-Life Scenarios
- An electronic grocer uses real-time validation checks to intercept zero-dollar price glitches before customers complete payment.
- A regional diagnostic center applies immediate notifications so blood analysis reports never stall during midnight database synchronizations.
- A metropolitan transport authority automates commuter card reconciliations so finance directors receive spotless revenue sheets every morning.
- A cloud video service relies on distributed message streams to observe playback buffering rates across millions of connected televisions.
DataOps Engineer Career Path
A focused DataOps Engineer architects, streamlines, and guards the automated pathways that move information throughout an organization. To succeed in this specialty, you must command Python syntax, SQL queries, Linux utilities, and Git version control. You must also discover how to construct automated unit checks, configure cloud instances, and manage complex job dependencies. Beginners can initiate their journey by writing a straightforward script that extracts public census records from an open repository. Sanitize that raw text with Python, store the rows within a local database, and showcase crisp findings on a dashboard.
Common Mistakes to Avoid When Choosing Delhi Events
- Finalizing reservations before locating the physical venue on navigation apps triggers severe transit delays across crowded roadways.
- Neglecting to determine whether an arena features an open-air roof creates unpleasant conditions during unexpected regional storms.
- Disregarding published parking guidelines leaves drivers searching jam-packed neighborhood streets for scarce open stalls for hours.
- Arriving without reviewing venue prohibited items lists leads to security personnel confiscating personal bags, power banks, and equipment.
- Overlooking explicit minimum age restrictions can disrupt an outing planned with young youngsters or older relatives.
- Skipping the official performance schedule causes you to arrive after principal headline acts conclude their sets.
- Procuring printed passes from unauthorized street brokers leads to sorrow when counterfeit tickets fail at turnstile scanners.
- Ignoring traditional dress code traditions brings unnecessary embarrassment or outright admission denial at heritage venues.
How TheDataOps.org Can Help
TheDataOps.org provides clear educational articles detailing DataOps Training, DataOps Certification, and every foundational DataOps Course. Students can review comprehensive walk-throughs covering leading DataOps Tools, DataOps Platform architectures, and effective DataOps Consulting approaches. The platform breaks down Data Pipeline Automation, Data Observability, and Data Quality Management into plain concepts. If you seek to establish yourself as a capable DataOps Engineer, this learning destination supplies practical roadmaps to fuel your daily studies.
Popular Tools Overview
| Tool | Main Use | Simple Example |
| Python | Data coding | Clean data |
| Airflow | Job scheduling | Run pipelines |
| Kafka | Data streaming | Move live events |
| Spark | Data processing | Process large data |
| Jenkins | Automation | Run tests |
| Grafana | Monitoring | Watch system health |
Frequently Asked Questions
1. What core problem does modern pipeline methodology solve?
Enterprises adopt this practice to deliver verified facts without recurring delays or broken tables. By aligning code developers with operational analysts, data flows predictably each day. Automation sweeps away repetitive manual labor, helping leaders make confident choices, delight customers, and drive revenue growth safely.
2. How does programmatic automation shield pipelines from human slipups?
Code executes unambiguous logic sequences repeatedly without experiencing fatigue, distraction, or careless oversights during high-volume transfers. It extracts records, applies tests, and writes final tables along strict schedules. Eliminating manual mouse clicks prevents accidental copy-paste mishaps, keeps storage tidy, and frees personnel to pursue innovative development initiatives.
3. Why does pristine data matter so much to managers?
Senior managers base product releases, capital distributions, and hiring plans upon dashboard indicators. Incomplete records, repeated transactions, or incorrect dates cause leaders to misunderstand market reality and squander capital. Strict quality filters intercept corrupt entries at ingestion, preserving management trust in daily operational summaries.
4. How does observability function inside enterprise tech architectures?
Observability inspects infrastructure components from within to reveal subtle snags before they erupt into catastrophic outages. It records transmission velocity, row volumes, arrival punctuality, and script failures around the clock. When a pipeline stalls, observability monitors fire immediate warnings so technicians resolve the anomaly before staff members arrive.
5. Can career changers grasp modern pipeline mechanics easily?
Motivated learners can master fundamental concepts through steady study, genuine curiosity, and routine terminal practice. You do not need deep mathematical brilliance to grasp how records move between database endpoints. Following hands-on walk-throughs and assembling personal portfolio apps creates rock-solid technical assurance day by day.
6. Why do instructors urge aspiring engineers to study Python first?
Beginners prioritize Python because its clean grammatical layout mirrors natural written sentences. The ecosystem includes thousands of free community modules tailored specifically for reorganizing raw records and recalculating numerical columns. Combining Python mastery with basic database query syntax equips you to tackle entry-level pipeline tasks comfortably.
7. What benefits do cloud environments bring to data distribution?
Cloud hosting providers allow companies to lease scalable server fleets and limitless storage capacity over network lines. Organizations process massive workloads without maintaining expensive computer racks that sit dormant in office utility closets. Cloud configurations also allow computing power to expand dynamically whenever seasonal buyer activity surges.
8. Why do developers embed automated tests inside data tracks?
Software engineers insert programmatic validations to catch abnormal figures, vacant inputs, and irregular arrangements before rows land in warehouses. These checks act like digital inspectors auditing shipping freight at border crossings. Halting dubious entries early prevents downstream visualization sheets from showing deceptive, embarrassing organizational figures.
9. How does pipeline operations differ from standard data engineering?
Data engineering concentrates on architecting and assembling the core pathways that transport raw information between destinations. Operations introduces automated testing, relentless health telemetry, rapid release rules, and shared team communication to that infrastructure. It guarantees that assembled pathways operate efficiently, securely, and predictably over long periods.
10. How do automated notifications prevent business headaches?
Real-time alarms notify on-call infrastructure specialists through text alerts or chat channels the exact second a pipeline task faults. Instead of discovering dead dashboards through angry manager phone calls, the team reacts immediately. This swift response enables developers to repair bugs before daily business operations begin.
11. Must a growing business purchase every trending application?
Sensible enterprises never buy every trending software product simply because marketing write-ups praise them. Every business manages distinctive file sizes, strict deadlines, and individual staff competencies. Selecting a compact set of dependable tools that eradicate your actual operational bottlenecks works far better than overcomplicating your architecture.
12. How do structured online materials accelerate technical careers?
Quality online guides teach authentic industry practices, review standard toolsets, and clarify intricate server systems. They deliver enjoyable, hands-on portfolio challenges that demonstrate your technical abilities to prospective employers. Working through these practical exercises positions you to pass technical screening exams and secure industry credentials.
Conclusion
Systematic pipeline practices transform tangled storage volumes into dependable business assets through smart automated sequences. By introducing continuous automated checks, holistic observability, and strict quality rules, teams banish manual drudgery and stop system crashes. Studying modern applications and earning relevant credentials prepares you to secure an exciting role as a DataOps Engineer. Learning sites like TheDataOps.org provide clear, progressive guidance that supports your professional advancement from complete novice to capable practitioner. Launch your journey today by writing a basic script, building an automated pipeline, and developing great operational habits.
