Introduction
Today, millions of people depend on fast apps, web games, and digital shopping carts every single hour. Site Reliability Engineering guarantees that these vast online systems stay awake, react swiftly, and never collapse under heavy traffic. Essentially, software developers write smart code to automate routine computer maintenance. This modern field unites programming expertise with everyday computer server operations. Talented developers build self-defending software designs so massive web platforms endure peak holiday spikes without crashing. SRESchool.com acts as a specialized global learning institute and enterprise solutions hub that teaches these critical modern disciplines.
What Is SRESchool.com?
True reliability means a computer application delivers great results every single time someone visits it. Consider a home refrigerator that preserves food day and night without unexpected temperature jumps. Software development teams want digital websites to run with that exact level of consistent endurance. Site Reliability Engineering gives technical teams the power to operate software products smoothly without sudden interruptions. Specialists continuously track server metrics, spot bugs quickly, and write automated routines that fix common glitches immediately. Furthermore, they inspect past operational mistakes so severe platform outages never occur again.
Why Does SRESchool.com Matter?
Every modern digital service relies on huge cloud networks, complex databases, custom code, and high-speed data lines. When one small server component breaks down, countless active users might suddenly lose access to their personal accounts. Using reliability engineering stops these minor hiccups from escalating into company-wide digital disasters. Coders track real-time health signals and resolve hidden bottlenecks before regular customers hit frozen screens. Adopting reliability as a routine engineering practice keeps organizations efficient, profitable, and secure.
What Does an SRESchool.com Team Do?
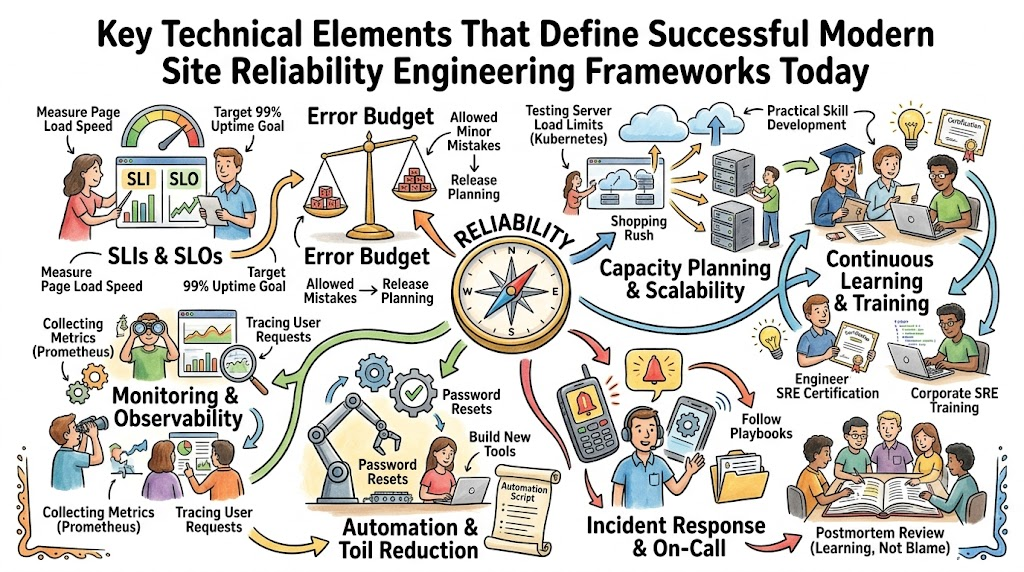
These dedicated engineers monitor system performance, configure alarm triggers, and fix sudden computer outages fast. They create helpful automation scripts that wipe out boring, manual keyboard tasks completely. In addition, these technicians forecast future computer memory demands so servers never choke during surprise visitor surges. They run thorough architecture reviews to catch potential security and speed flaws before public users stumble upon them. After every major technical breakdown, the entire team meets to write actionable steps that improve future operations.
Section 5: Key SRE Terms Made Easy
Reliability professionals use distinct technical terms to evaluate platform performance and record user speeds. An SLI acts as an active metric measuring real-time operations, like server response speed. An SLO represents the target goal that the engineering group promises to deliver. An error budget outlines the tiny pocket of downtime that a team can safely risk when publishing new features. Toil means tedious, repetitive manual work that a basic software script could easily perform instead. Observability helps specialists understand internal platform health simply by examining external telemetry data. On-call describes an engineer carrying a live pager to fix sudden overnight platform emergencies immediately. An incident marks an unplanned software disruption that damages normal user experiences.
| SRE Term | Simple Meaning | Example |
| SLI | An active metric showing true performance speed. | Tracking the percentage of search queries returning in under two seconds. |
| SLO | A target benchmark that engineers aim to satisfy. | Promising that the checkout cart works ninety-nine percent of the time. |
| Error Budget | Safe room for trial and error during feature releases. | Allowing fifteen minutes of total downtime across thirty days. |
| Toil | Routine manual maintenance that creates zero permanent value. | Clearing out full hard disk logs by hand every single evening. |
| Observability | Assessing inner system health through external signals. | Studying latency graphs to identify a jammed background task. |
| On-call | Holding an alert device to resolve unexpected outages. | Monitoring an automated alert pager during a major holiday sale. |
| Incident | An unexpected breakdown that impairs software quality. | A payment gateway that rejects user credit card inputs without warning. |
What Is SRE Training?
Rigorous SRE Training introduces newcomers to practical methods for shielding large cloud servers against sudden failures. Students examine basic system principles, define sensible reliability benchmarks, and read real-time health monitors. They also study observability, incident handling, automated scripts, capacity planning, and toil reduction. Practicing directly within sandbox production networks reinforces fundamental skills and builds lasting technical confidence. Ambitious learners find clear guided lessons and interactive exercises on SRESchool.com to conquer these vital industry tasks.
What Is SRE Certification?
An accredited SRE Certification confirms that an engineer knows how to keep business software running smoothly under extreme loads. A Certified Site Reliability Engineer understands how to measure live uptime, establish service targets, and squash production bugs. Structured curriculum tracks guide technical workers through core principles in an organized manner. However, a paper credential alone cannot substitute for real hours spent repairing broken infrastructure. Genuine career growth comes from diagnosing faulty code, deploying test networks, and resolving simulated emergencies under tight deadlines.
What Is a Site Reliability Engineering Course?
An engaging Site Reliability Engineering Course walks a student through a clear, gradual educational pathway. Learners start with fundamental concepts, construct real-time monitoring boards, and set sensible operational goals. Next, they practice resolving simulated outages, coding maintenance scripts, and defending distributed cloud architectures. This practical, hands-on path equips novices and seasoned software engineers alike with valuable skills for top technology jobs.
SRE Tools Made Simple
Modern software companies rely on specialized software suites to keep massive computing platforms operating smoothly. Monitoring applications observe machine status, and dashboard screens convert raw server numbers into readable graphs. Logging platforms capture error notices, while tracing systems track single user actions through complex web microservices. Alert notification managers sound urgent alarms during emergencies, and automation engines fix broken components automatically. Well-known programs like Prometheus, Grafana, and OpenTelemetry help technical teams isolate flaws and patch bugs before customers ever complain.
| Learning Area | What Learners Can Practice |
| System Monitoring | Setting automated alarm triggers whenever network traffic doubles suddenly. |
| Visual Dashboards | Assembling interactive panels to display CPU temperatures and memory usage. |
| Log Management | Sifting through application logs to pinpoint faulty database commands. |
| Distributed Tracing | Tracking an electronic fund transfer across six connected cloud servers. |
| Task Automation | Writing an active script that clears temporary folders without human intervention. |
| Incident Drills | Participating in unannounced drills to restore disconnected servers rapidly. |
Real-Life Scenarios / Experiences
- An online retail store absorbs an enormous customer surge by spinning up fresh cloud instances through automatic scaling rules.
- A site engineer receives an automated alert concerning low storage capacity and triggers a script that purges old log files.
- A video streaming platform detects rising lag times on a live dashboard and restarts sluggish servers within seconds.
- A financial payment app reviews a sudden transaction slowdown, writes a thorough post-incident report, and installs stronger code guardrails.
What Is SRE Consulting?
Independent SRE Consulting brings seasoned outside specialists into an organization to identify hidden infrastructure weaknesses. These knowledgeable consultants audit existing monitoring suites, set balanced reliability objectives, and refine emergency response procedures. They also pinpoint repetitive manual chores and design clear roadmaps for complete task automation. This direct, expert assistance prevents costly web outages and ensures business software operates with absolute dependability.
What Is SRE as a Service?
Selecting SRE as a Service grants growing companies ongoing, direct access to experienced platform engineers. These external professionals supervise platform monitoring, resolve sudden production alarms, and perform regular system architecture reviews. They also manage cloud capacity, write custom automation routines, and forecast long-term system resource requirements. Businesses must identify their operational needs clearly to get the highest return from these specialized services.
What Is Corporate SRE Training?
Targeted Corporate SRE Training unites an entire engineering staff behind shared software maintenance methods. The curriculum focuses on the employer’s active tool stacks, unique incident protocols, and practical automation scripts. Teammates align around common service benchmarks, explore dashboard configurations, and practice live disaster recovery scenarios together. Shared laboratory projects build smooth communication channels and confirm that all staff members know how to fix production outages.
Common Mistakes to Avoid When Choosing Reliability Methods
- Running manual machine tests instead of deploying automated tracking agents for live health oversight.
- Choosing extreme uptime goals that stop creative programmers from launching fun application features.
- Accepting boring repetitive tasks instead of building automated software tools to handle them cleanly.
- Silencing alert bells as unimportant noise until an essential cloud component stops working entirely.
- Bypassing post-incident discussions instead of detailing why an application crashed during business hours.
- Purchasing high-priced enterprise software suites before teaching junior staff the basics of service health.
- Overlooking future data limits until heavy consumer traffic crashes internal database engines.
- Keeping application programmers and operations technicians in separate silos that refuse to exchange operational data.
How SRESchool.com Can Help
SRESchool.com delivers focused educational materials and dedicated technical guidance to boost application uptime. Learners explore foundational SRE Training, practical SRE Certification programs, and a modular Site Reliability Engineering Course. The site also features an accessible SRE Tutorial collection along with clear breakdowns of modern SRE Tools. Furthermore, businesses can select targeted SRE Consulting, dependable SRE as a Service arrangements, or comprehensive Corporate SRE Training. These balanced offerings prepare modern technical teams to protect vital applications and build strong cloud platforms.
Frequently Asked Questions
1. What daily duties does a reliability specialist handle?
Engineers track system metrics, deploy automated scripts, and solve live server crashes throughout the day. They calibrate practical performance goals, inspect recent software rollouts, and eliminate dull manual chores. This ongoing routine protects critical web applications and ensures customers enjoy dependable digital platforms.
2. How does this methodology differ from classic DevOps?
DevOps unites development and operations groups to deliver new software code quickly and reliably. This discipline uses focused software programming techniques to tackle daily operational challenges and stop service crashes. You can view it as a concrete way to achieve core DevOps targets safely.
3. What does an error budget mean in plain words?
An error budget describes the small amount of safe downtime an application can experience over time. Technical crews use this buffer to decide when to deploy daring updates or halt experimental rollouts. When systems remain exceptionally stable, programmers launch new features with greater creative freedom.
4. How do SLIs differ from SLO targets?
An SLI tracks actual real-time metrics, like how fast an online search returns customer results. An SLO is the target speed that the technical staff promises to maintain all month long. Comparing the actual metric to the target shows whether the service satisfies user expectations.
5. Can a novice learn these operational principles easily?
Every beginner can pick up these ideas if they tackle the basics first and practice consistently. Reading simple guides, viewing health dashboards, and creating small scripts develops deep technical confidence. Structured internet lessons and realistic lab tasks turn this learning curve into an enjoyable journey.
6. Why do repetitive chores harm software teams?
Toil involves boring, manual administrative chores that require constant human effort without producing new value. When technicians spend entire shifts on dull tasks, they lack time to build lasting system improvements. Removing repetitive chores frees up engineers to construct faster, stronger digital products.
7. Why do technical crews draft post-incident summaries?
Technical crews write incident reports after outages to learn how the system broke and why safeguards failed. These objective reviews examine system designs rather than pointing fingers at individual staff members. Teams use the resulting action items to upgrade defenses so the exact same problem never repeats.
8. Which programs should a student try out first?
Students should begin with accessible data collection software like Prometheus and visual chart utilities like Grafana. These widely used programs display server changes clearly through neat graphical dashboards. After grasping the visual basics, learners can move toward task automation scripts and cloud utilities.
9. What advantages come from group corporate instruction?
Group instruction ensures every staff member uses identical terms, consistent tools, and shared reliability targets. It improves how internal teams configure alerting rules, handle production panics, and automate daily infrastructure duties. This collective understanding minimizes costly downtime and keeps internal software pipelines moving smoothly.
10. Does a passing certificate ensure on-the-job mastery?
A certificate proves that an applicant understands essential concepts, service targets, and routine operational guidelines. However, true workplace mastery requires practical experience troubleshooting broken cloud platforms under real pressure. The strongest engineers blend formal testing credentials with plenty of hands-on scripting and problem-solving practice.
11. What value does observability offer modern tech companies?
Observability allows engineers to diagnose mysterious software bugs by analyzing system outputs, event records, and performance metrics. Instead of guessing why a service runs slowly, technicians inspect hard operational data directly. This total visibility helps teams resolve root causes and squash glitches before customers complain.
12. How does professional consulting assist growing companies?
Targeted consulting helps organizations evaluate infrastructure health, uncover risky blind spots, and improve performance tracking suites. Seasoned advisors help internal groups create practical reliability benchmarks and streamline their emergency repair routines. This actionable advice stabilizes complex cloud setups while reducing long-term maintenance costs.
CONCLUSION
Running large web networks, enterprise software, and mobile applications requires rigorous discipline every single day. Teams rely on constant monitoring, automated code, and objective performance targets to stop bugs before users ever experience downtime. Anyone can master these career-defining abilities through structured video courses, step-by-step documentation, and official technical credentials. Simultaneously, evolving businesses can leverage specialized advisory solutions and managed operational services to protect their cloud infrastructure. Platforms like SRESchool.com provide the essential educational tracks and enterprise support that technical teams need to achieve lasting software performance.
